iFANN
    iFANN durchsuchen...
    Anmelden
    Startseite
    Nachrichten
    Videos
    Fotos
    GIFs
    Entdecken
    Umfragen
    Auszeichnungen
    iFAMOUS
    Wiki
    Anime
    Räume
    Benachrichtigungen
    Nachrichten
    Lesezeichen
    Profil
    WikiAuszeichnungeniFAMOUSRanglistenBranchenCreator-BelohnungenBenutzerbelohnungenNutzungsbedingungenDatenschutzCommunity-RichtlinienEntfernung / DMCAHilfeEntwickler

    © 2026 iFANN

    Startseite
    Suche
    Nachrichten
    Alarme
    Profil
    Foto
    Nate
    Nate@nate_5123mo
    📱Qwen💭AI💭Tech
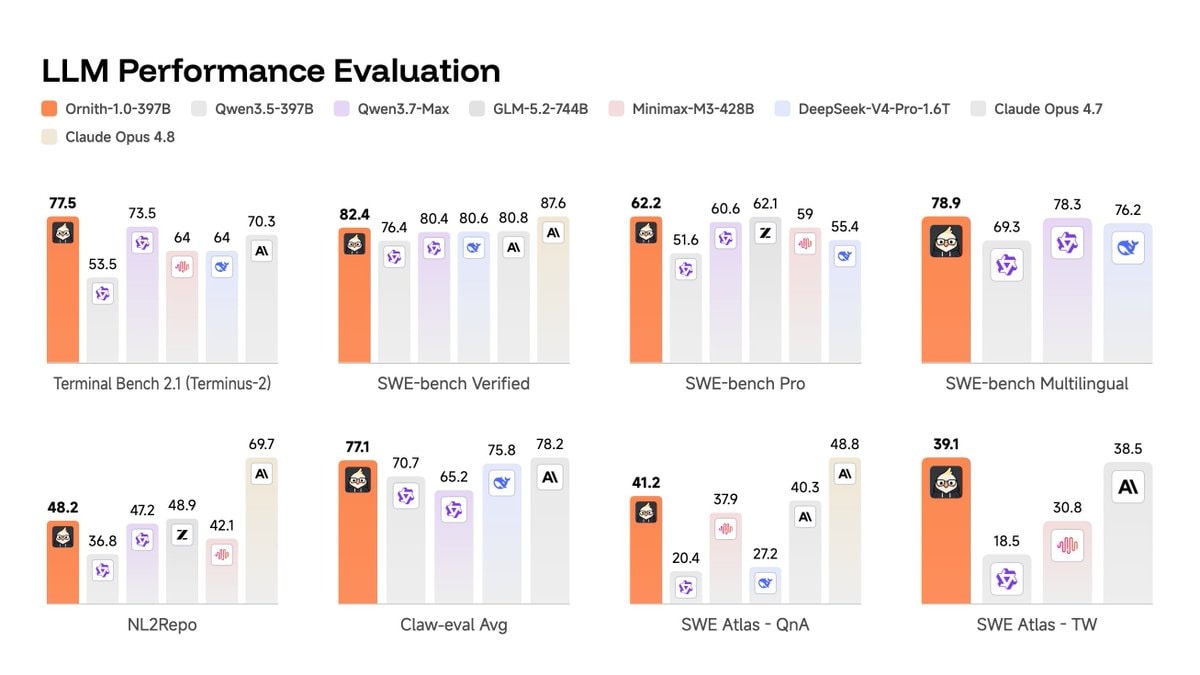
    Ornith-1.0 agentic coding LLM performance

    @nate_512Open-source models are quickly catching up to proprietary ones in agentic coding tasks. The release of the Ornith-1.0 family shows that a closed API isn't necessary for achieving state-of-the-art coding agent performance. Built on Gemma 4 and Qwen 3.5, Ornith employs a self-scaffolding reinforcement learning pipeline. Details at the link.

    Originalbeitrag ansehen
    Ornith-1.0 agentic coding LLM performance

    Foto von @nate_512· Jun 27, 2026· Qwen

    Über dieses Foto

    The image shows a bar graph comparing the performance of various LLM models. The focus is on the graph titled "LLM Performance Evaluation". The graph displays the performance of multiple models across several benchmarks. The mood/style is formal and technical. A notable detail is the color-coded legend at the top, which differentiates between the models. There is no on-screen text beyond the title and labels, which read "LLM Performance Evaluation", "Terminal Bench 2.1 (Terminus-2)", "SWE-bench Verified", "SWE-bench Pro", "SWE-bench Multilingual", "NL2Repo", "Claw-eval Avg", "SWE Atlas - QnA", and "SWE Atlas - TW".

    Alle Fotos von Qwen ansehenQwen-Wiki lesen

    ?

    Noch keine Kommentare. Sei der Erste!

    Mehr Fotos von Qwen

    Alle Fotos von Qwen ansehen
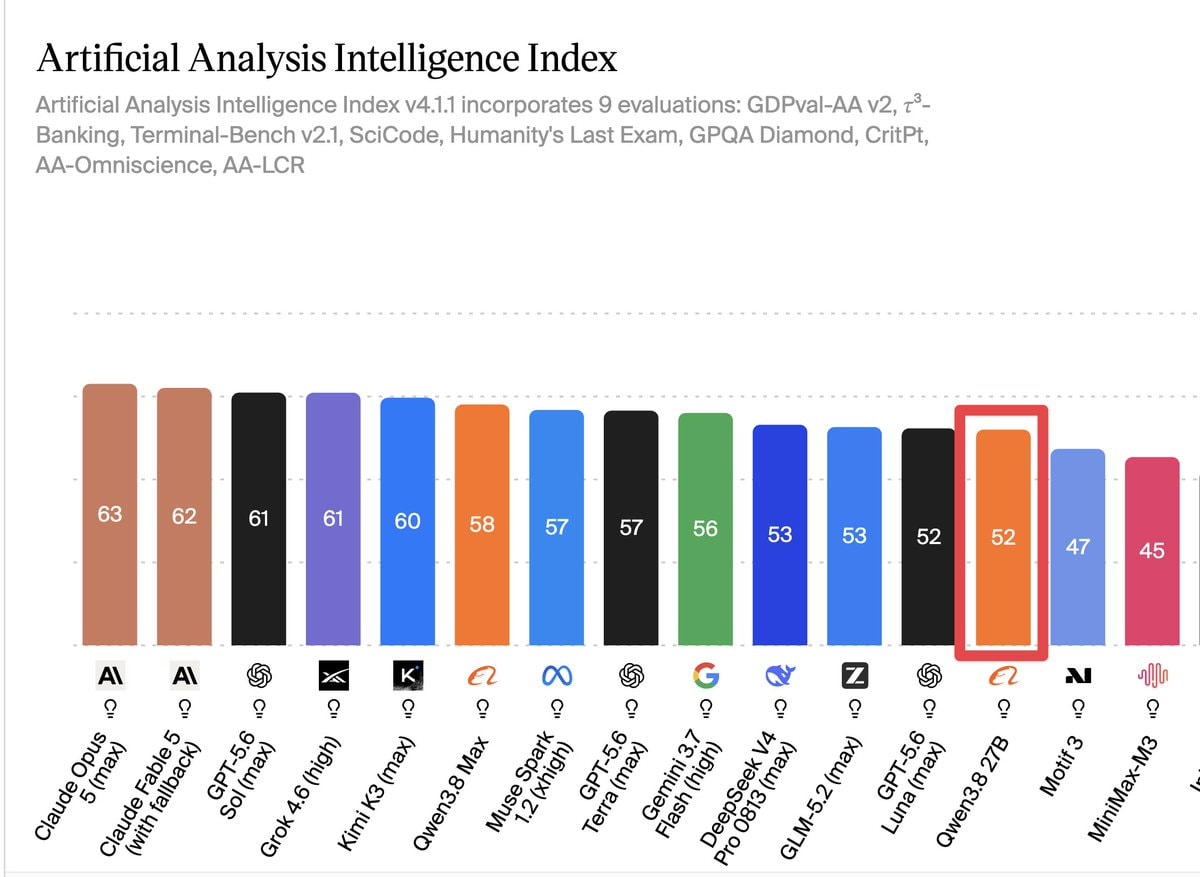
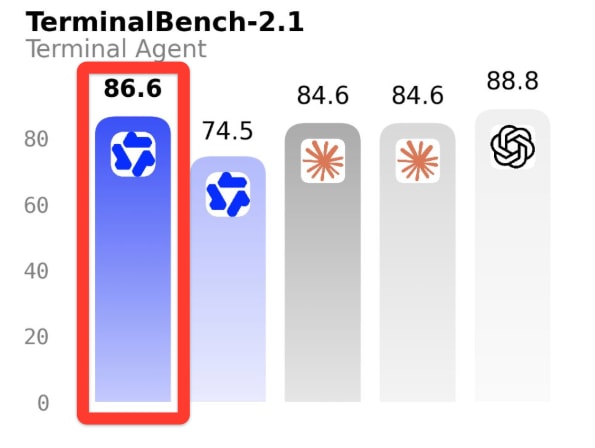
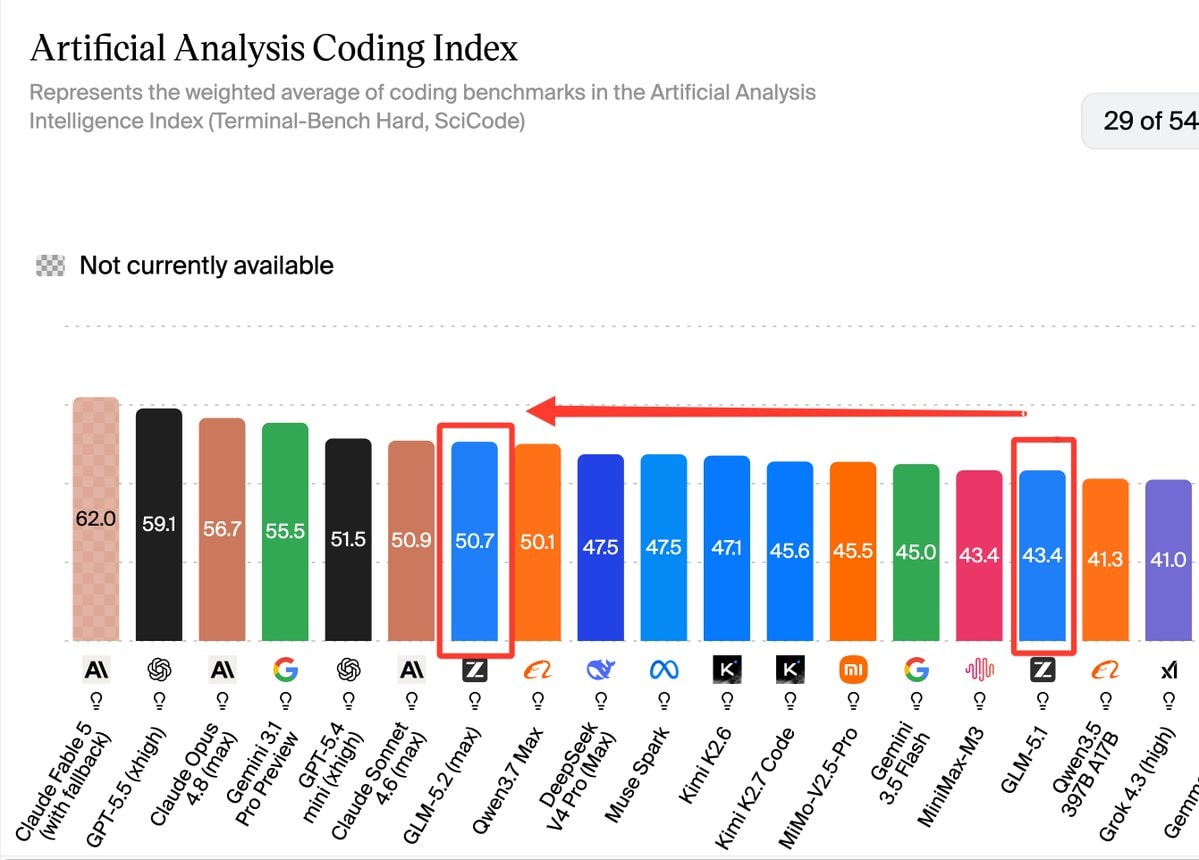
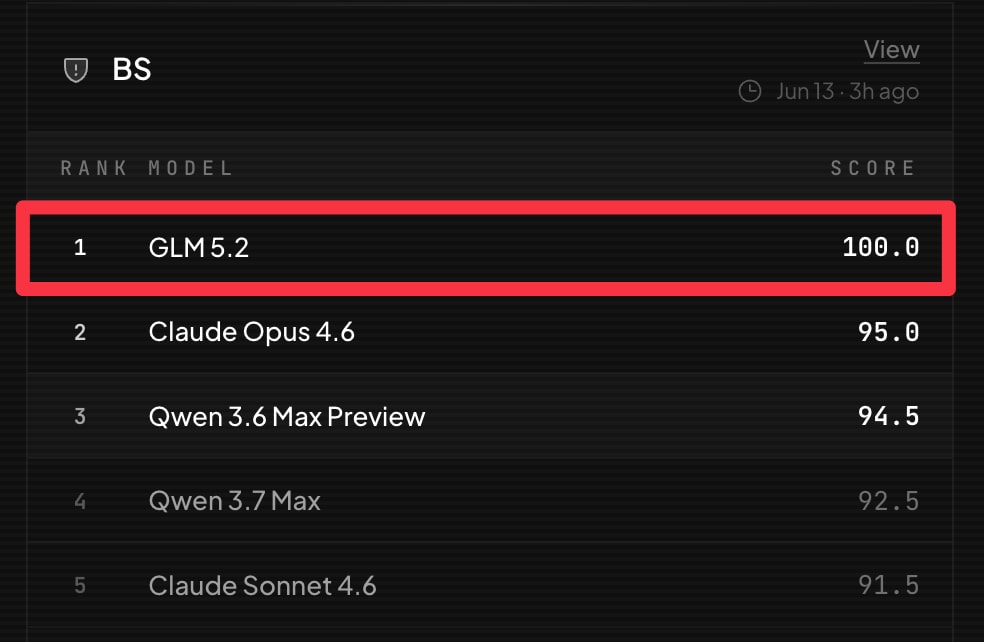
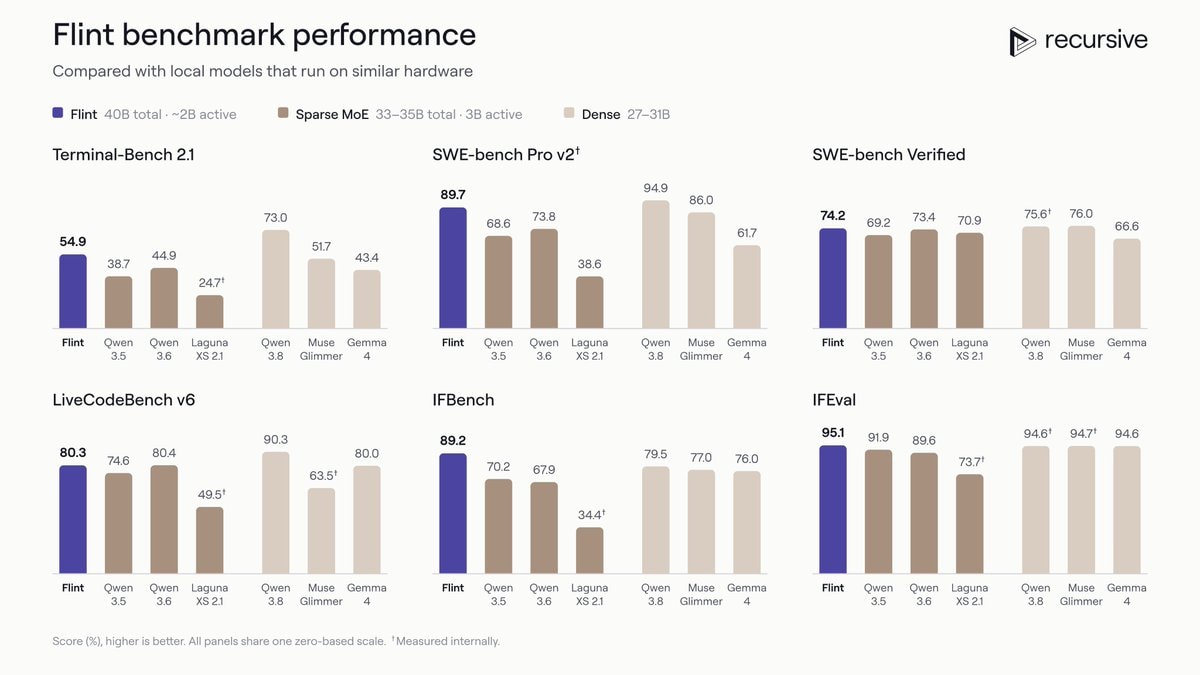
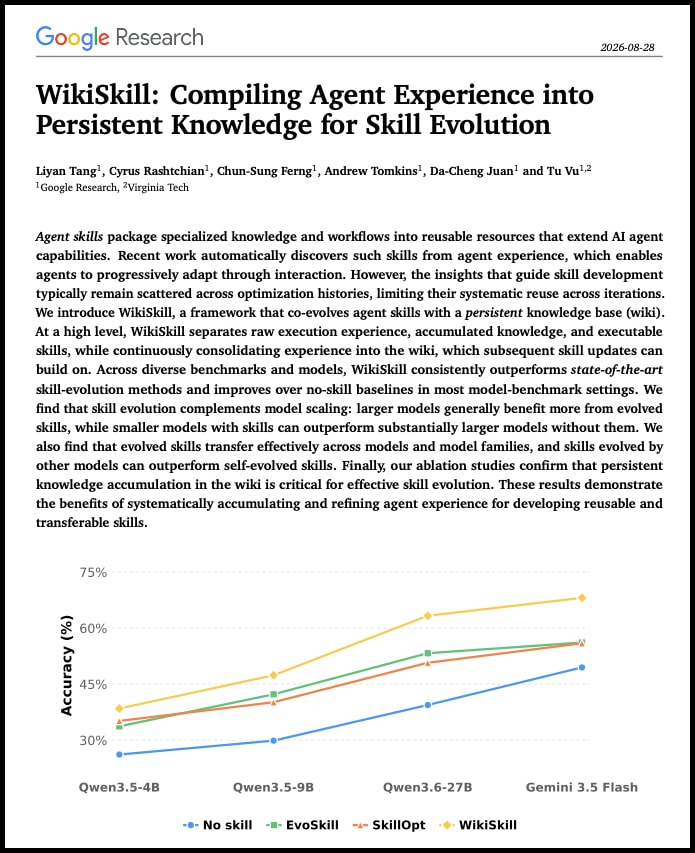
    Flint benchmark performance vs local modelsFlint benchmark performance vs local modelsGoogle WikiSkill paper SKILL.md agentsGoogle WikiSkill paper SKILL.md agentsAI models Kimi Qwen DeepSeek GLM MiniMaxAI models Kimi Qwen DeepSeek GLM MiniMaxQwen 3.8 27B ties GPT 5.6 LunaQwen 3.8 27B ties GPT 5.6 LunaQwen 3.8 Max TerminalBench scoreQwen 3.8 Max TerminalBench scoreGLM 5.2 Artificial Analysis Coding IndexGLM 5.2 Artificial Analysis Coding IndexGLM 5.2 perfect score BridgeBench BSGLM 5.2 perfect score BridgeBench BS
    Foto
    Nate
    Nate@nate_5123mo
    📱Qwen💭AI💭Tech
    Ornith-1.0 agentic coding LLM performance

    @nate_512Open-source models are quickly catching up to proprietary ones in agentic coding tasks. The release of the Ornith-1.0 family shows that a closed API isn't necessary for achieving state-of-the-art coding agent performance. Built on Gemma 4 and Qwen 3.5, Ornith employs a self-scaffolding reinforcement learning pipeline. Details at the link.

    Originalbeitrag ansehen
    Ornith-1.0 agentic coding LLM performance

    Foto von @nate_512· Jun 27, 2026· Qwen

    Über dieses Foto

    The image shows a bar graph comparing the performance of various LLM models. The focus is on the graph titled "LLM Performance Evaluation". The graph displays the performance of multiple models across several benchmarks. The mood/style is formal and technical. A notable detail is the color-coded legend at the top, which differentiates between the models. There is no on-screen text beyond the title and labels, which read "LLM Performance Evaluation", "Terminal Bench 2.1 (Terminus-2)", "SWE-bench Verified", "SWE-bench Pro", "SWE-bench Multilingual", "NL2Repo", "Claw-eval Avg", "SWE Atlas - QnA", and "SWE Atlas - TW".

    Alle Fotos von Qwen ansehenQwen-Wiki lesen

    ?

    Noch keine Kommentare. Sei der Erste!

    Mehr Fotos von Qwen

    Alle Fotos von Qwen ansehen
    Flint benchmark performance vs local modelsFlint benchmark performance vs local modelsGoogle WikiSkill paper SKILL.md agentsGoogle WikiSkill paper SKILL.md agentsAI models Kimi Qwen DeepSeek GLM MiniMaxAI models Kimi Qwen DeepSeek GLM MiniMaxQwen 3.8 27B ties GPT 5.6 LunaQwen 3.8 27B ties GPT 5.6 LunaQwen 3.8 Max TerminalBench scoreQwen 3.8 Max TerminalBench scoreGLM 5.2 Artificial Analysis Coding IndexGLM 5.2 Artificial Analysis Coding IndexGLM 5.2 perfect score BridgeBench BSGLM 5.2 perfect score BridgeBench BS