iFANN
    iFANN durchsuchen...
    Anmelden
    Startseite
    Nachrichten
    Videos
    Fotos
    GIFs
    Entdecken
    Umfragen
    Auszeichnungen
    iFAMOUS
    Wiki
    Anime
    Räume
    Benachrichtigungen
    Nachrichten
    Lesezeichen
    Profil
    WikiAuszeichnungeniFAMOUSRanglistenBranchenCreator-BelohnungenBenutzerbelohnungenNutzungsbedingungenDatenschutzCommunity-RichtlinienEntfernung / DMCAHilfeEntwickler

    © 2026 iFANN

    Startseite
    Suche
    Nachrichten
    Alarme
    Profil
    Foto
    Nate
    Nate@nate_51221h
    🏢Hugging Face📱GitHub💭AI
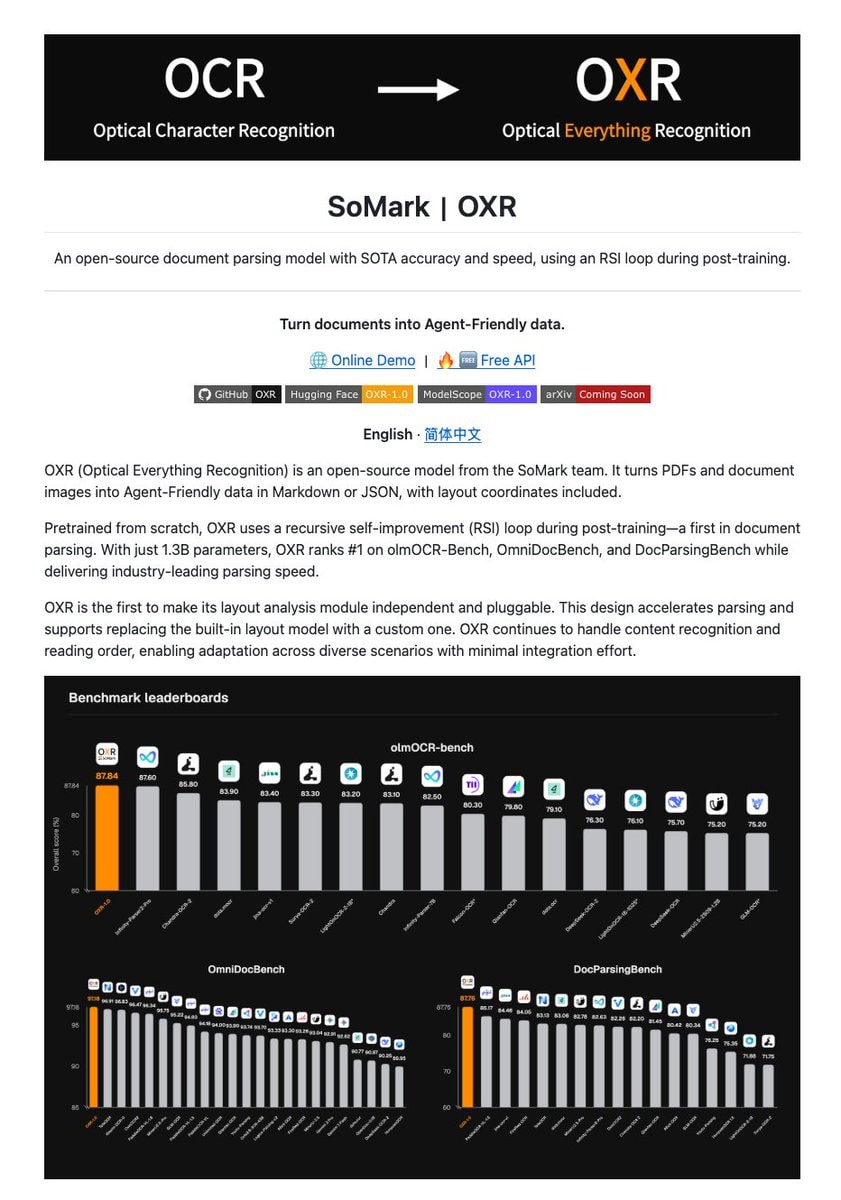
    SoMark OXR OCR benchmark results

    @nate_512SoMark | OXR is flipping parsing errors into specific training data without needing manual labels. The RSI loop takes unlabeled documents, runs them through a VLM to spot disagreements, clusters the failure causes, generates targeted data, and retrains the model automatically. This 1.3B parameter setup actually tops olmOCR-Bench, OmniDocBench, and DocParsingBench. On a single RTX PRO 6000 GPU it crushed a 100-page OmniDocBench test in 101 seconds, hitting 2.52 times the throughput of MinerU2.5-Pro. It's described as the fastest open-source parser tested for Optical Everything Recognition. The project is free and open-source with links on GitHub, Hugging Face, ModelScope, and arXiv.

    Originalbeitrag ansehen
    SoMark OXR OCR benchmark results

    Foto von @nate_512· Oct 23, 2026· Hugging Face

    Über dieses Foto

    The image is a screenshot of a webpage detailing a project called SoMark | OXR. It focuses on Optical Character Recognition (OCR) and Optical Everything Recognition (OXR) technology. The page describes OXR as an open-source document parsing model with benchmark leaderboards for different performance metrics. The mood is informative and technical, presented in a clean, modern design. Visually notable elements include the prominent branding of "OCR" and "OXR" at the top, and the bar charts displaying benchmark results with various icons representing different models. ON-SCREEN TEXT: OCR Optical Character Recognition OXR Optical Everything Recognition SoMark | OXR Turn documents into Agent-Friendly data. Online Demo | Free API GitHub OXR Hugging Face OXR-1.0 ModelScope OXR-1.0 arXiv Coming Soon English · 简体中文 Benchmark leaderboards olmOCR-bench OmniDocBench DocParsingBench

    Alle Fotos von Hugging Face ansehenHugging Face-Wiki lesen

    ?

    Mehr Fotos von Hugging Face

    Alle Fotos von Hugging Face ansehen
    Ariana Grande AI videos flagged for copyright2Ariana Grande AI videos flagged for copyrightAmazon AI chips unused warehouse2Amazon AI chips unused warehousePeter Steinberger OpenClaw investment2Peter Steinberger OpenClaw investmentSylvester Stallone on AI inevitability2Sylvester Stallone on AI inevitabilityMC Cabelinho Brazil national football team jacket2MC Cabelinho Brazil national football team jacketU.S. banks AI security2U.S. banks AI securityYahoo hiring Marty McFlyYahoo hiring Marty McFlyMidjourney preference questionMidjourney preference questionFlint benchmark performance vs local modelsFlint benchmark performance vs local modelsSpotify removes 50M AI slop tracksSpotify removes 50M AI slop tracks
    Foto
    Nate
    Nate@nate_51221h
    🏢Hugging Face📱GitHub💭AI
    SoMark OXR OCR benchmark results

    @nate_512SoMark | OXR is flipping parsing errors into specific training data without needing manual labels. The RSI loop takes unlabeled documents, runs them through a VLM to spot disagreements, clusters the failure causes, generates targeted data, and retrains the model automatically. This 1.3B parameter setup actually tops olmOCR-Bench, OmniDocBench, and DocParsingBench. On a single RTX PRO 6000 GPU it crushed a 100-page OmniDocBench test in 101 seconds, hitting 2.52 times the throughput of MinerU2.5-Pro. It's described as the fastest open-source parser tested for Optical Everything Recognition. The project is free and open-source with links on GitHub, Hugging Face, ModelScope, and arXiv.

    Originalbeitrag ansehen
    SoMark OXR OCR benchmark results

    Foto von @nate_512· Oct 23, 2026· Hugging Face

    Über dieses Foto

    The image is a screenshot of a webpage detailing a project called SoMark | OXR. It focuses on Optical Character Recognition (OCR) and Optical Everything Recognition (OXR) technology. The page describes OXR as an open-source document parsing model with benchmark leaderboards for different performance metrics. The mood is informative and technical, presented in a clean, modern design. Visually notable elements include the prominent branding of "OCR" and "OXR" at the top, and the bar charts displaying benchmark results with various icons representing different models. ON-SCREEN TEXT: OCR Optical Character Recognition OXR Optical Everything Recognition SoMark | OXR Turn documents into Agent-Friendly data. Online Demo | Free API GitHub OXR Hugging Face OXR-1.0 ModelScope OXR-1.0 arXiv Coming Soon English · 简体中文 Benchmark leaderboards olmOCR-bench OmniDocBench DocParsingBench

    Alle Fotos von Hugging Face ansehenHugging Face-Wiki lesen

    ?

    Mehr Fotos von Hugging Face

    Alle Fotos von Hugging Face ansehen
    Ariana Grande AI videos flagged for copyright2Ariana Grande AI videos flagged for copyrightAmazon AI chips unused warehouse2Amazon AI chips unused warehousePeter Steinberger OpenClaw investment2Peter Steinberger OpenClaw investmentSylvester Stallone on AI inevitability2Sylvester Stallone on AI inevitabilityMC Cabelinho Brazil national football team jacket2MC Cabelinho Brazil national football team jacketU.S. banks AI security2U.S. banks AI securityYahoo hiring Marty McFlyYahoo hiring Marty McFlyMidjourney preference questionMidjourney preference questionFlint benchmark performance vs local modelsFlint benchmark performance vs local modelsSpotify removes 50M AI slop tracksSpotify removes 50M AI slop tracks