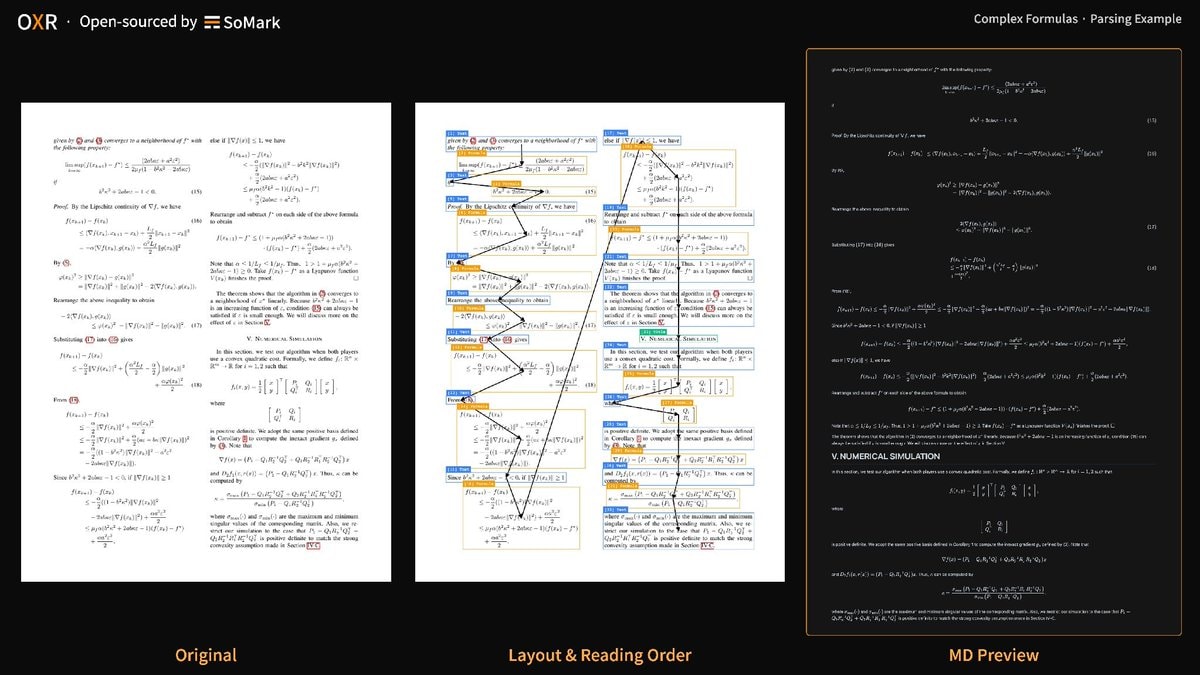
@nate_512PDFs come in and get mangled the moment tables, formulas and columns get flattened to plain text, which is the mess OXR was built to avoid. The model packs 1.3 billion parameters and outputs structured Markdown or JSON from PDFs and document images, with spatial coordinates and reading order baked into the result. Thirteen document element types fall under its coverage, chemical structures among them. Anyone wiring up RAG or document pipelines has a real reason to care here, since handling gnarly structures well is half the battle. SoMark put it out open source, so go dig in
Originalbeitrag ansehen
Noch keine Kommentare. Sei der Erste!