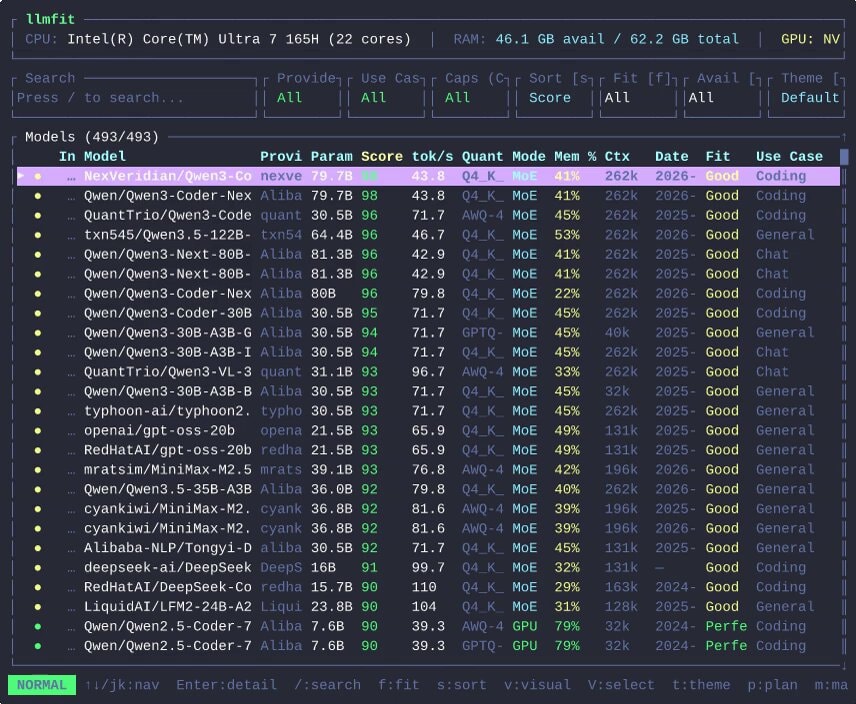
llmfit hardware scanner for local LLMs
So you see a model with a massive parameter count and think your rig can handle it, right? llmfit exists to check that impulse before you waste bandwidth. It scans your actual setup, RAM, CPU, GPU(s), VRAM or unified memory, then runs the numbers on which language models will genuinely work for you. Every model gets judged on quality, speed, fit, and context window support, and the verdict comes back as Perfect, Good, Marginal, or Too Tight. The tool even auto-picks the optimal quantization level, so you don't have to manually wrestle with GGUF file sizes. Support spans hundreds of models from Meta, Mistral, Qwen, DeepSeek, and others. It hooks straight into Ollama, llama.cpp, MLX, and LM Studio with zero extra configuration. Plus, you get a text interface, a web dashboard, and REST API endpoints for slotting into your pipeline. Honestly, this should be the first step before any local model download. It's free, open-source, and runs on macOS, Linux, and Windows.